Thursday, January 8, 2015

Rameia's Fast Plant Mini-Lab Report

Rameia Ramsey
Analysis
In this Fast Plant lab we planted and grew Wisconsin Fast Plants. By growing these  plants we were able to see what kind of data we would be working with and then manipulate the experiment to produce results that we wanted and would expect. In order to successfully do this we first planted a parent generation which would serve as the foundation for out other generations.  We continued to grow,water, and monitor the plants over a 35 day period in a classroom with the plants sitting on a watering system under fluorescent lighting.  After the growth of our first set of plants, there were a variety of leaf lengths. On day 9 we counted the amount of leaves grown and recorded the leaf lengths of the plants. Our sample size was 57 plants and the leaf lengths of the parent generation ranged from 2mm to 25mm with the average leaf length being about 9mm.  Through the process of artificial selection we decided to  keep plants with a leaf length of 12mm and over.  All of the other plants that did not meet this requirement were cut out and removed. After removing the plants that did not meet the requirements our sample size decreased to just 8 plants.  This meant we had killed off about 85% of the original parent generation.  With the surviving plants we did various calculations to determine the mean, standard deviation, standard error mean, and 95% confidence intervals of the plants.  From there we used bees to pollinate the surviving plants in order to create seed pods to use for the F1 generation. After we planted the newly formed seed pods we then planted them to create the F1 generation.  After this generation grew, we had observed the plants and decided on a question to test.
image.png
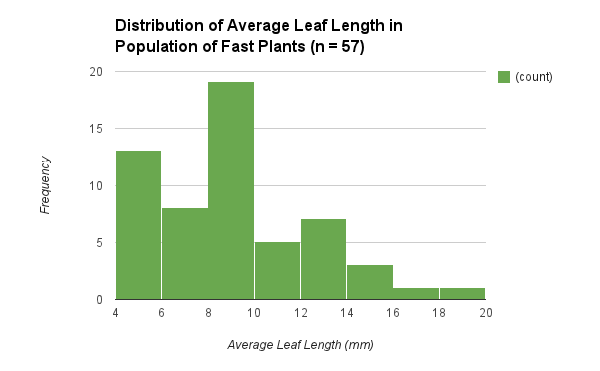
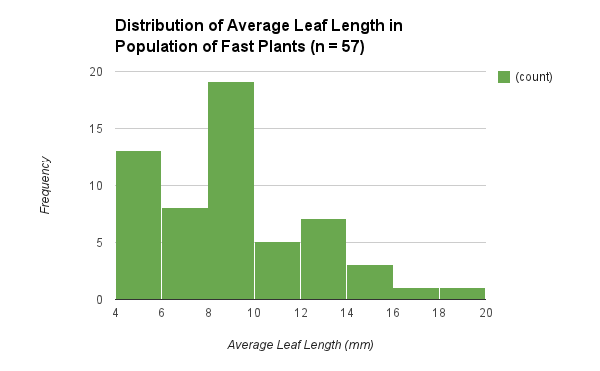
After the growth of the parent generation, we reached a sample size of 57 plants.  The plants varied in length but there was definitely a higher number of plants who had an average leaf length of about 9mm which is relates to the the mean of the all 57 plants being 8.83mm.  The median of the leaf lengths was 8.5mm so we can assume that our calculations are accurate.  We tested the standard error of the mean which tests the limits of the mean, meaning it accounts for other factors that could influence the mean of the plants.  The SEM of this generation was 0.45mm.  We also calculated the 95% confidence interval which helps to be 95% confident that the mean of our data only varies from other data by chance.  The upper 95% interval  was 9.74mm and the lower limit was 7.94mm.  In the graph shown you can see that there is a bell curve to the data collected.  Based on the data for this generation we used it as a foundation to figure out what we going to manipulate.  We found that there were very little amount of plants with leaf lengths of 12mm and above so we decided to keep those plants and pollinate them for future generations to be made.
Screen Shot 2014-12-14 at 11.07.27 PM.png
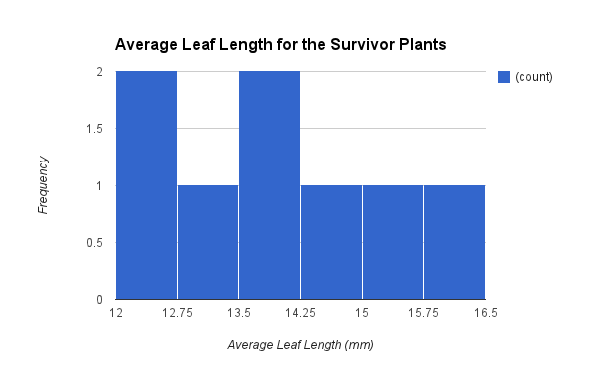
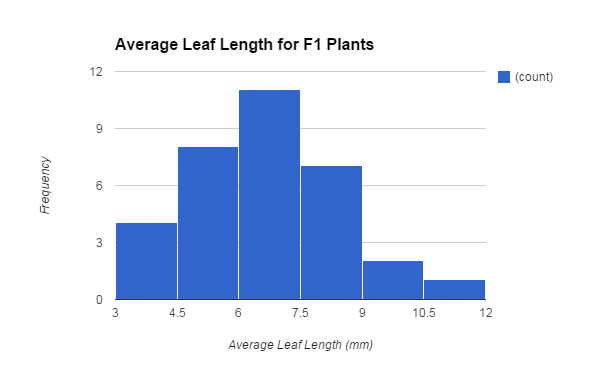
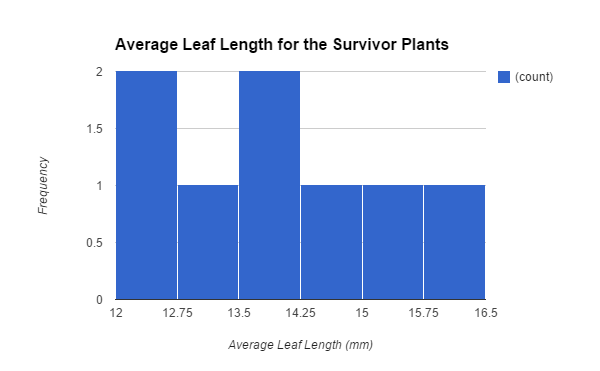
After we had killed of 85% of the parent generation so that we only had plants with leave lengths of 12mm or more remaining, there were only 8 plants that remained.  Out of this group of plants there was not much of a variety of the leaf length.  The average leaf length for this group was 13.88mm, with the median being 13. 75mm again showing the accuracy of the data.  The SEM of this group of plants was exactly .45mm.  The 95% confidence interval for the upper limit was 14.78mm and the lower limit was 12.98mm.  There is definitely a significant difference between the survivors and the original parent generation.  Considering we have selected for taller plants we expect that the generation we breed for will be similar to this group and not the original parent generation.  The graph here also shows how there isnt a bell curve to the data either.  This data we collected was then used as a comparison for the F1 generation plants.    Screen Shot 2014-12-14 at 11.09.02 PM.png   After pollinating the survivors of the parent generation, we came to have and F1 generation sample size of 32 plants. In this generation, there was more variety of the leaf lengths similar to like there was in the parent generation with the  the average leaf length being  6.46mm, this number being significantly lower than both the parent generation and the survivor generation.  The 95% confidence interval upper was 7.09mm and the lower limit was 5.83mm, again lower than the parent and surviving generation.  Throughout the generations none of the confidence intervals overlap which shows how our null hypothesis is rejected because there is a significant difference between all of the means of average leaf length for each generation. Our null hypothesis of this experiment was that there is no significant difference between the average leaf lengths of the parent generation and the F1 generation.  As a result of the experiment we reject the null hypothesis.   

Discussion
Conclusion:
This experiment modeled the effects of artificial selection on the Wisconsin fast plants.  This experiment proved that what is expected to happen does not occur as we were expecting to see that parent generation and F1 generation were to be similar.  There means as seen in the first and last figure are significantly different.  Also the confidence intervals do not overlap which means that there is a significant difference between the two generations.  This proves that we reject our null hypothesis. The graphs for the parent generation and F1 generation are also different.  The F 1 generation has shifted to the left which is the opposite of the extreme that we had selected for. With all of this information to look back upon I can make an assumption that the length of the leaves may not be a trait that is passed down even when you only experiment with one extreme of the leaf lengths.  Some of the limitations of the experiment could have affected our data could be the amount of seeds that actually grew into plants.  There were most likely some seeds that did not grow or plants that did not develop enough in order for us to count them as part of the population.  If there were more plants they could have potentially been apart of the survivor generation and help to contribute and pollinate for the F1 generation.  

Experimental Evaluation:

With the results from our experiment for the most part I feel confident that our numbers are correct.  But there are some factors and situations that could have contributed to slight errors in our numbers that could give us potentially a less than accurate result.  I feel as though most of the error that could have occurred was human error not an error of any instruments used. There could have been errors in the parent generation when measuring the leaf lengths of the 57 plants.  There was not one person designated to measuring, we were all measuring and counting different plants.  There is a very good chance that there could have been a misreading of the measurements and not accurate counting of the amount of plants.  We most likely don’t all have the same reasoning when we try to figure out the measurement of an object or deciding on whether or not to count a specific plant as developed or not. This in turn would have affected how many plants we had in the survivor generation and thus affect our results in the F1 generation.  Also, when we left our plants to grow in the classroom under the flourescent lights and on top of the water system we were not always checking up on them as we were supposed to.  So this could have also affected the growth of the plants and further affect the results we received. The light received by each of the plants could have also affected our results.  We never kept up with measuring how far away each of the plants were from the light, so not all of the plants were receiving equal amounts of light based on their positions which could have affected the growth of the plants.  

Wednesday, January 7, 2015

Joshua Everett's Mini Wisconsin Fast Plant Lab Report

Everett Wisconsin Fast Plant Lab Report


The Effect of Artificial Selection on Wisconsin Fast Plants

The purpose for performing this lab is to model artificial selection within Wisconsin Fast Plants. As a class, we chose the characteristic of average leaf length of the plants to be selected for in which a change in the average leaf length would be predicted in the offspring from the parent generation. The research question we are trying to answer is: does the selection for the average leaf length influence the phenotypes of the offspring? The results of the experiment showed that the research question is not supported by the data that my classmates and I collected.
In the beginning of the experiment, a parent generation of fifty seven Fast Plants was grown within planting units each having four pods. In each pod a diamond wick, planting soil, fertilizer seeds, and fast plant seeds were placed respectively in this order. They were grown continuously for approximately 40 days before the offspring plants were grown. All plants, however, were place on top of a water reservoir to ensure the plants maintained ideal water levels. All plants were also under cool-white fluorescent lights to allow plants to perform metabolic process and grow. After approximately five days the average leaf lengths for each of the plants were recorded (Figure 1). The averages for the leaf lengths vary continuously from plant to plant. (Figure 1). There is no relationship shown between the average leaf length for each plant in which there is no bell curve. The average leaf lengths for the plants are heavily concentrated between four to six millimeters and between eight and ten millimeters. The outliers for this graph are the average leaf length between six and eight millimeters and from ten to twenty millimeters. (Figure 1). The most concentrated averages and the outliers are not integrated in the graph to where a pattern is shown. The data is not normally distributed because if it was, a bell curve would be shown in which the sloping sides would contain the outliers and the curve would contain the average leaf lengths that  are most concentrated by the plants. Another account for why the data is skewed is because the standard deviation is 3.39 which is higher than the standard deviation for the survivors (1.26) and F1 generation (1.81). There is more variation of the data here which explains why the data is not more evenly dispersed. Even though a pattern is not depicted, the curve of the bell curve represents the mean of all the average leaf lengths for the parent generation plants which is 8.839181287.  

image.png
Figure 1
From the information from figure one, it was decided by my classmates and I that the leaf lengths under 12 mm was to be selected against. To implement this selection pressure, the class trimmed the leaves of all the plants that had a leaf length of twelve millimeters and below. The outcome the my classmates and I were expecting to see in the survivor parent population were all plants with leaf lengths of  twelve millimeters and over. The average leaf lengths for each plant for the survivors after selection were recorded (Figure 2). There is a significant decrease in the population of the parent population to the survivor population in which the parent population has 57 plants and the survivor population only has 8 plants. The frequency of higher average leaf length is significantly lower than in the original parent population when compared to the survivor population. To make this conclusion, the means of the parent population and the survivor population was compared. The parent population mean is 8.84 and the survivor population mean is 13.88. The average leaf length increased after the selection pressure was implemented. Because all leaf length under twelve millimeters were selected again, only leaf lengths above twelve millimeters were left. This caused a shift in the graph from eight to ten millimeters in the parent population to 13.5 millimeters to 14.5 millimeters. In addition, the dispersion and variation of the data for the survivor population is smaller than that of the parent population. This is accounted from through the standard deviations of the two populations. The standard deviation for the parent population is 3.39 but the survivor population has a standard deviation of 1.26. The smaller the standard deviation, the less variation and dispersion of the data. The standard deviation also accounts for the lack of fluctuation in the graphs because of the lack of variation and dispersion which is why the graph lacks a bell curve. On another note, the SEM of the survivor population is 0.45 and the 95% confidence interval for the survivor population is from 12.98 to 14.78. For the parent population, however, the SEM is 0.45 and the 955 confidence interval is from 7.94 to 9.74. The confidence intervals show the range of the where the means will lie if the experiment is performed again. Since the confidence intervals from the survivors population and the parent population do not overlap, I can conclude that the means for both populations are significantly different from each other. This would imply that the selection pressure that was implemented was a success.
image (1).png
Figure 2


Using the survivors population, my classmates and I performed sexual reproduction with the plants by cross pollinating the plants using bee sticks. If the process is done correctly the plants will produce produced seed pods which  are then used to plant the F1 generation. After letting the offspring grow for approximately nine days, we measured their leaf lengths for each plant a recorded them (figure 3).
The graph now depicts a bell curve in which the data is evenly distributed and an average leaf length can be roughly seen. The mean of the F1 generation is 6.462121212 which is different from the parent population and the survivor population in which their means were 8.84 and 13.88 respectively.  The average leaf length shifted along the graph in which it is not the same as the survivor population but it is similar to the parent population in which the average leaf length now ranges from 6 millimeters to 7.5 millimeters. The means of the parent population and the F1 generation are more similar than that of the survivor population. The standard deviation for the F1 generation is 1.81 which is higher than the survivors standard deviation which is only 1.26. The standard deviation is high for the F1 generation because there were more plants in the F1 generation (33) than the survivors generation (8) which increase the variation in the plants. To ensure that the mean of the F1 generation is not similar to the survivor population, the 95% confidence intervals were compared. The definition of similar or not similar is determined through 95% confidence intervals. The null hypothesis that is used to see if the survivors generation is similar to the F1 generation for is that there is no significant difference between the mean of the original population and the mean of the F1 generation.The SEM of the original population is 0.4492766416 and the SEM for the F1 generation is 0.3146201419. These SEM’s provide the range in which the confidence interval will range based on 5% built in error if the experiment was performed again. The upper and lower confidence intervals for the original survivor population is 14.78 and 12.98 respectively. The upper and lower confidence intervals for the F1 generation is 7.091361496 and 5.832880928 respectively. These confidence intervals do not overlap at any point in time which means that is a significant different between the mean of the survivor generation and the F1 generation. The null hypothesis failed to be rejected in this situation.

Figure 3

Discussion
Conclusions:
The results of the experiment does not support the research question because even though the means are different from each other, the mean of the  F1 generation is lower than the mean for the original population and the survivor parent population. If directional selection was inflicted on the parent population and affected the phenotypes of the offspring, we would expect for the  mean of the offspring to be greater than the original parent population and similar to the mean of the survivor parent population. We directionally selected for plants with average leaf lengths of 12mm and higher in which we wanted to have offspring with average leaf lengths of 12mm or larger but that was not the case. The average leaf lengths are instead smaller than the survivor parent population. The 95% confidence interval for the parent population is from 7.94 to 9.74 and the confidence interval for the F1 generation is from 5.83 to 7.09. The confidence intervals do not overlap which means that the means of the two populations are significantly different from each other. They are significantly different from each other in which the F1 generation has a lower mean than the parent population.  Through these comparisons, I can conclude that the research question was not fully supported by the experiment. After continually analysing the results of the experiment, I came to the conclusion that genetics did not have a role in this experiment but the results were rather an act of randomness. I had an outcome of what I wanted the outcome of the experiment to be and the results were not matching up. I wanted the mean of the F1 generation to similar to the mean of the survivors or even higher. In this experiment we were focused on phenotypes and genotypes so genetics was not a factor in this experiment in which genes of larger average leaves would not have passed down to the next generation. There were a couple limitations of the experiment. Specifically, one limitation would include that not all of the parent generation seeds grew into plants for the selection process to take place and to produce offspring. The seeds that did not bloom could have possibly had leaves of 12 mm or higher that could have affected the results of the experiment in some way.

Experimental Evaluation:
I do not feel 100% confident in the results I obtained because we only did one trial of the experiment. Performing multiple trials of the same experiment can confirm or refute the results obtain in the first trial. Performing multiple trials solidifies your experiment and an average of some sort can be calculated to incorporated all the results of each trial. Looking back on the lab, I would have been more organized in my notes and data. Many times throughout the experiment there was confusion on what day of the experiment we were on and there was confusion on what data belonged to which plant. At times there was a lot of confusion but as the experiment went on, it became easier to anticipate what we were doing. I do not believe there were any intentional human errors in this lab. The class followed the procedure to the experiment very well. Any sources of error in this lab comes from random errors. When planting the send and growing the parent generation, an error in planting the seeds, like forgetting fertilizer, could affect the growth of the plant which could affect the results of the experiment. Another source of error would be not keeping the plants hydrated at all times. Sometimes the water reservoir was not seeping up water through the cloth to be pulled up to the plant through the time. Many times we found our plants dry and hard. This characteristic of the soil of the plant could also affect growth and development and reproduction. Lastly, another source of error could have derived from measuring, Many times, it was difficult and very tedious to measure each leaves length. Error in measurement could have affected the selection and the over results of the experiment. I do not have any changes or improvements to make for this lab. The only thing I would do different is to just perform this experiment without the distractions of any other activities. In class, a lot of time was spent on other activities focused on other parts of the curriculum. Many time the students of the class forgot about the plants are lost track of the step of the procedure we were on. This is another potential error source that I would want to eliminate if I were to perform this experiment again.


Jazmean's Wisconsin Fast Plants Mini Lab

Jazmean Williams


The Effect of Selection Pressures on the Average Leaf Length of Wisconsin Fast Plants


Research Question and Hypothesis


Research Question: Does selection for average leaf length in the Parent Generation influence F1 phenotypes?


Hypothesis: Selection for longer leaf lengths in the P Generation results in a longer leaf average in the F1 Generation due to directional selection.


Results


P Generation Pre-Selection
After planting the seeds and giving them time to grow, the class observed the plants on Day 5 of the experiment. Discussion ensued after looking at the plants and we decid selection process. We then gathered data from the plants. For the P Generation before selection, there were 57 plants. Each student in the class measured the leaf lengths of each plant quad (Figure 1). The measurements of the average leaf lengths of each separate plant aided in deciding which plants were able to stay in the experiment and which ones were cut. After finding what the average leaf lengths were, we graphed the data in the form of a histogram (Figure 2). This was done to see if there was a variation of leaf lengths in this generation and if leaf length was a trait that could be used in the selection process. The histogram showed that there was a variation of leaf lengths in the P Generation and that leaf length could be used in the selection process. The class determined that we were going to selected against small leaf lengths and we chose 12mm as our cut off length. This means that if at least one of the leaves of the plants were 12mm or more, they stayed. If the plant contained no leaves that were at least 12mm, they were cut. The average leaf length of each plant also helped in determining the median and mean leaf length of the P Generation which was 8.5mm and was 8.839mm respectively. We also found the Standard Deviation, SEM, and Confidence Intervals of this generation. Figure 3 shows all of the data collected from the P Generation before selection.

Figure 1


Figure 2


Figure 3


P Generation
Sample Size (n)
57
Mean
8.839181287 mm
Median
8.5 mm
Standard deviation
3.39196426 mm
SEM
0.4492766416 mm
95% CI Lower Limit
7.940628004 mm
95% CI Upper Limit
9.73773457 mm


P Generation After Selection
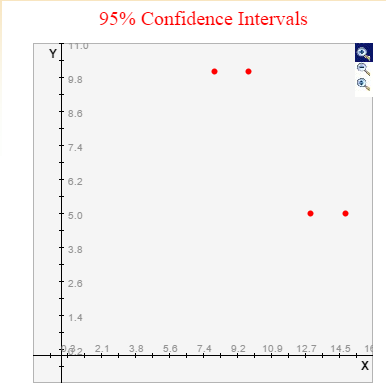
After the P Generation underwent the selection process, only 8 plants remained. We calculated the mean and median of the survivor generation which were 13.88 mm and 13.75 mm respectively (Figure 4).  We also calculated the average leaf lengths of the plants and made a histogram of the data (Figure 5). The histogram provided us with a visual representation to see if the leaf lengths were 12mm and above and we selected correctly. To reaffirm that we really did the selection process correctly, we found the Standard Deviation and SEM which helped us find the Upper and Lower Confidence Intervals of the P Generation Survivors. We then compared the intervals with the P Generation Confidence Intervals. Confidence Intervals gives us the parameters of a population. They provide a range of values that, with a certain degree of confidence (in this case, 95%), tell us where the “true” population values fall. If the Confidence Intervals of the P Generation and the P Generation Survivors overlap, we know that they both have a chance of having a plant with the same leaf length. We do not want this since we are selecting against leaf lengths shorter than 12mm. The overlap between the two intervals would also tell us that we did our selection process wrong. Luckily, the two confidence intervals did not overlap (Figure 6). Knowing this allowed us to continue with our experiment. We cross pollinated the plants on Days 12 to 16 of the experiment. After drying the seed pods, we counted 54 seeds in total and replanted them.


Figure 4


P Generation - Survivors
Sample Size (n)
8
Mean
13.88 mm
Median
13.75 mm
Standard deviation
1.26 mm
SEM
0.45 mm
95% CI Lower Limit
12.98 mm
95% CI Upper Limit
14.78 mm


Figure 5


Figure 6

95% confidence intervals.png


(Top dots are P Generation and bottom dots are P Generation Survivors)


F1 Generation
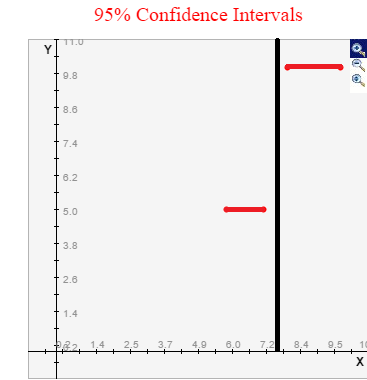
Out of the 54 seeds that were planted, only 33 sprouted and grew into plants. We then measured the leaf lengths of each plant and took the average. After that, we calculated the mean and the median. Right away we saw that the mean and the median of the F1 Generation was lower than that of the P Generation (Pre-Selection). The mean and the median of the F1 Generation were 6.46 mm and 6.33 mm respectively (Figure 7), while the mean and median of the Parent Generation were 8.839 mm and 8.5 mm respectively. With this in mind, we continued and made a histogram of the average leaf length of the F1 Generation to visually see the distribution of the leaf lengths (Figure 8). The histogram shows that the majority of the plants had an average leaf length between 6mm and 7.5mm which lines up with the values we found for the mean and median. We then found the Standard Deviation, SEM, and Confidence Intervals. We compared the confidence intervals of the F1 Generation and Parent Generation to see if there was any overlap. Figure 9 shows that there was no overlap between the two generations. Because there was no overlap, with a 95% degree of certainty, we can say that the F1 Generation and P Generation do not have the same leaf length values.


Figure 7


F1 Generation
Sample Size (n)
33
Mean
6.462121212
Median
6.333333333
Standard deviation
1.80735
SEM
0.3146201419
95% CI Lower Limit
5.832880928
95% CI Upper Limit
7.091361496


Figure 8
The top line is the P Gen and the bottom line is the F1 Gen. The black line between the two red lines helps distinguish the gap between the two intervals. 

95% confidence intervals2.png


Discussion


Conclusions
We can reject our hypothesis and say that selecting for longer leaf lengths in the P Generation did not result in a longer leaf average in the F1 Generation. Evidence for this is that the mean of the F1 Generation is less than the mean of the P Generation. This means that the average leaf length for the F1 Generation is less than the Parent Generation’s average leaf length.  Also, the CI of the F1 Generation is a lower range of values than the P Generation. The parameters of the F1 population is between 5.83 mm and 7.09 mm and for the P Generation, it is between 7.94 mm and 9.74 mm. This shows that the true value of the F1 Generation is less than the true value of the P Generation, or that the F1 Generation is expected (with a 95% degree of certainty) to have a leaf length that is smaller than that of the Parent Generation. We can also conclude that there is a possibility that leaf length is not a genetic trait. If it is not a genetic trait and the leaf lengths occur at random, it would make sense that any selection pressure we would use would not work. In order to definitely conclude this, I believe that at least 2 more trials need to be conducted. These results are surprising. I did not expect to see the average leaf length of the plants to decrease instead of increase. I was under the assumption that leaf length was a genetic trait, however, I know now that it might not be the case.


Experimental Evaluation
I was uncertain with how the initial procedure would work because at the beginning, we all seemed pretty unsure of what to do. However, as the experiment progressed, I believed we gained a better understand of what we needed to do and what we should get out of this, especially since we were learning about evolution (more specifically artificial selection) during this time. Because of this, I feel pretty confident in how we conducted the experiment. Even though I feel confident in how we conducted the experiment, I still think there may have been some spots where human error may have skewed the results. We may have agreed on what constituted as the length of the leaf, but there may have been some misreadings of the leaf length measurements. We protected ourselves against human error in terms of calculating the mean, median, standard deviation, etc because we did it using Excel and the functions within the program.


In terms of limitations, I believe the fact that not all of the seeds in the P Generation grew for the selection process is one. Another one would be that not all the seeds in F1 Generation grew. The 21 seeds that did not grow may have been sides that had leaf lengths 12 mm and above which would change the outcome of the experiment. 

In terms of the results, I believe that we need to do at least two more trials to ensure of the validity of our results. I tried researching if there was any published material on the premise of our experiment, but there was nothing I could see. Because of that, there is no real way of knowing if leaf length is a genetic trait unless we do more trials.  


References
*Confidence Interval “definition” was adapted from the McGraw Hill Criminal Justice Book*

Nida Ali's Fast Plant Mini Lab

Nida Ali
Analysis


In this class collaborative lab, we examined the effect on the average leaf length   plays on Wisconsin Fast Plants based off of artificial selection.
Primarily, a histogram was constructed to display the leaf length of our first generation plants. However majority of the leaf lengths were similar to one another, which thus did not formulate a bell curve graph for the parent population before selection (Figure 1). Then the artificial selection part of the lab began when we began to select for traits that are able to display a bell curve based on collected data. We then collected the average leaf length of each individual plant and constructed the histogram below. As depicted, this histogram clearly displays a bell curve based off the average leaf length per plant rather than each individual leaf length on a plant. On average the mean of the parent population was 8.8mm and the median was 8.5mm. Most of the leaf lengths of the plants fall in 4mm-10mm mark and the outliers fall after the 14mm mark. The histogram below displays a bell curve mainly because of the 95% Confidence Intervals that is 7.94 to 9.74, the standard deviation of 3.39 and SEM of .45.


Figure 1


After day 9, we began to look for variation among the plants. We selected for plants with the longest leaf length of 12mm long as our variable trait since it varies within range and kept those leaves alive, which ended up being just 8 plants. Leaves the were under 12mm were cut off and no longer remained in this artificial plant selection lab. As shown in the histogram below of the parent population after selection (Figure 2), the average leaf length of plants dramatically altered through augmentation. The parent population after selection histogram below does not present a bell curve, unlike the histogram of P generation before selection (Figure 1), which thus states that the average leaf lengths were similar in height. Majority of the plants had an average leaf length between 12mm to 14.25mm. As for the mean, the average increased from 8.8mm, before selection from the parent population,  to 13.88mm after selection. Likewise, the median also increased from before and after selection of the parent population from 8.5mm to 13.75mm. The standard deviation had a minor decrease from the P generation before survivors from 3.39 to 1.26, which thus displays that among the plants, not much change/variation was depicted. 
Once the parent population survivors reproduced, the difference seen among the mean and 95% confidence intervals were much closer to the parent population before selection rather than the parent population after selection. We calculated 95% intervals in order to see if the artificial selection process was done correctly. If the 95% intervals overlapped, the average leaf lengths were similar. In contrast, if the 95% intervals did not overlap, the average leaf length were not similar. The 95% confidence intervals were not similar either which highlights that the two do not overlap. In addition, the SEM value of 4.449 remained relatively the same to that of the P generation before survivors.
Figure 2
A proper bell curve graph was seen after my classmates and I took measured the average leaf lengths for each plant that was pollinated with beesticks. During this process, only a few plants survived, in which we based the histogram below off of. The F1 generation histogram (Figure 4)  displays a better bell curve more than but similar to that of the parent generation before selection. The medium of the average leaf lengths is 6.3mm and the mean averaged out to 6.5mm. The SEM was of 0.31 and the standard deviation was 1.81. The selection for the parent generation before selection influences the F1 generation due to the similar values seen in the means, 95% lower limit and upper limit. While comparing the 95% confidence intervals of the upper and lower limit of the parent generation of 7.9 to 9.73 to that of the F1 generation of 5.8 to 7.09, they do not overlap resulting in less similarity.

Figure 4


Discussion
Conclusion:
The null hypothesis that there is no significant difference is seen between the two means of the parent generation before selection and F1 generation is rejected. We reject the null hypothesis because there is a significant difference among the means due to the difference seen in the P generation before selection and F1 generation 95% confidence intervals. The 95% confidence intervals do not overlap, which thus states that they were not similar. Since the leaf length means of the P generation Survivors and Offspring generation are not similar, the artificial selection for the average leaf length does not influence the offspring generations. Through this experiment, I can conclude that the role artificial selection does not largely impact generations since the trait that is selected against may in fact be randomly passed down through generations.
A few limitations occurred during this lab experiment. One limitation is that not all of the planted seeds were able to grow, which thus resulted in several plants dying out and not participating in the experiment. Therefore, our results ended up being based off of 8 plants total. In addition, another limitation is that we did not regularly monitor our plants due to the lack of time, in most cases. We only monitored the plants once the next step in the lab was about to be conducted. Therefore, if we were consistent in monitoring our plants, possibly more plants would have been produced and not dried out due to any shortages either to light or water. If more plants were produced during this lab, accurate results would have been seen.

Experimental Evaluation:
Several errors conducted during this experiment may have altered the end result of this lab if they were addressed earlier. First and foremost, a huge error that was conducted was not exactly keeping track of the days. If we focused on what needs to be done mandatory on certain days, then I believe we would have accurate results. By going a few days here and there may not, at first, seem like a massive implication, but it may massively alter our results by allowing the plants to grow a couple of more days. One common error is not properly averaging the leaf lengths. In most cases, this may have to do with the shortage of time which resulted in students to quickly rush their math conducting process. In addition, another error that may alter the end result of the experiment would be accurately trimming the plants that were no longer needed in this lab.
Even though this lab was very time consuming, considering the few months that it took to fully conduct this lab, I felt that the results we received were still sufficient to an extent regarding minor errors.